Practical AI reliability guide
When an AI answer sounds certain, it can still be wrong
AI hallucinations are invented or unsupported details presented as if they were true. This guide explains why they happen, how to recognize them, and how to verify AI-generated information before it affects a decision.
Last reviewed: September 2026
Generative AI can summarize a report, explain a difficult idea, draft code or organize a plan in seconds. Its fluency is useful, but fluency is not evidence. A chatbot can produce a confident explanation, complete with dates, quotations and citations, even when some of those details are incorrect or do not exist.
This behavior is commonly called an AI hallucination. The term can make the problem sound mysterious. In practice, it reflects how generative models work: they generate likely output from patterns rather than consult a perfect internal database of verified facts. If you are new to the underlying technology, start with our guide to generative AI.
Key takeaways
- An AI hallucination is a plausible-looking output that is false, unsupported or inconsistent with the supplied source.
- Hallucinations can include invented facts, fake citations, nonexistent product features, broken code and visual errors.
- A confident tone, detailed wording and a list of sources do not prove an answer is accurate.
- Clear prompts, current source material, retrieval, citations and human review can reduce risk, but no method removes it completely.
- The safest habit is simple: verify each important claim at the original source before using it.
What are AI hallucinations?
An AI hallucination occurs when a generative system produces content that appears meaningful and credible but is false, unsupported by the available evidence or unrelated to the requested source. The NIST Generative AI Profile uses the term confabulation for confidently stated erroneous or false content.
The mistake may be obvious, such as an impossible historical date. It may also be subtle: a real author paired with a nonexistent paper, a correct statistic attributed to the wrong year, a software function that sounds normal but is not part of the library, or a summary that adds a conclusion the source never made.
Hallucinations are different from deliberate deception. A language model does not need an intention to mislead. It can generate an inaccurate response because the wording fits the statistical patterns it learned. The result may still mislead a person, especially when it arrives in polished prose.
| Problem | What it means | Example |
|---|---|---|
| Hallucination | The model invents or presents unsupported information. | A citation names a journal article that does not exist. |
| Outdated information | The answer may once have been true but is no longer current. | A chatbot gives an old product price or former company policy. |
| Reasoning error | The supplied facts may be correct, but the conclusion does not follow. | A calculation uses the wrong denominator. |
| Bias | The output unfairly favors or disadvantages a group or viewpoint. | A hiring summary applies stereotypes to a candidate. |
| Prompt misunderstanding | The model answers a different interpretation of the request. | “Java” is treated as the island when the user meant the language. |
Why does AI hallucinate?
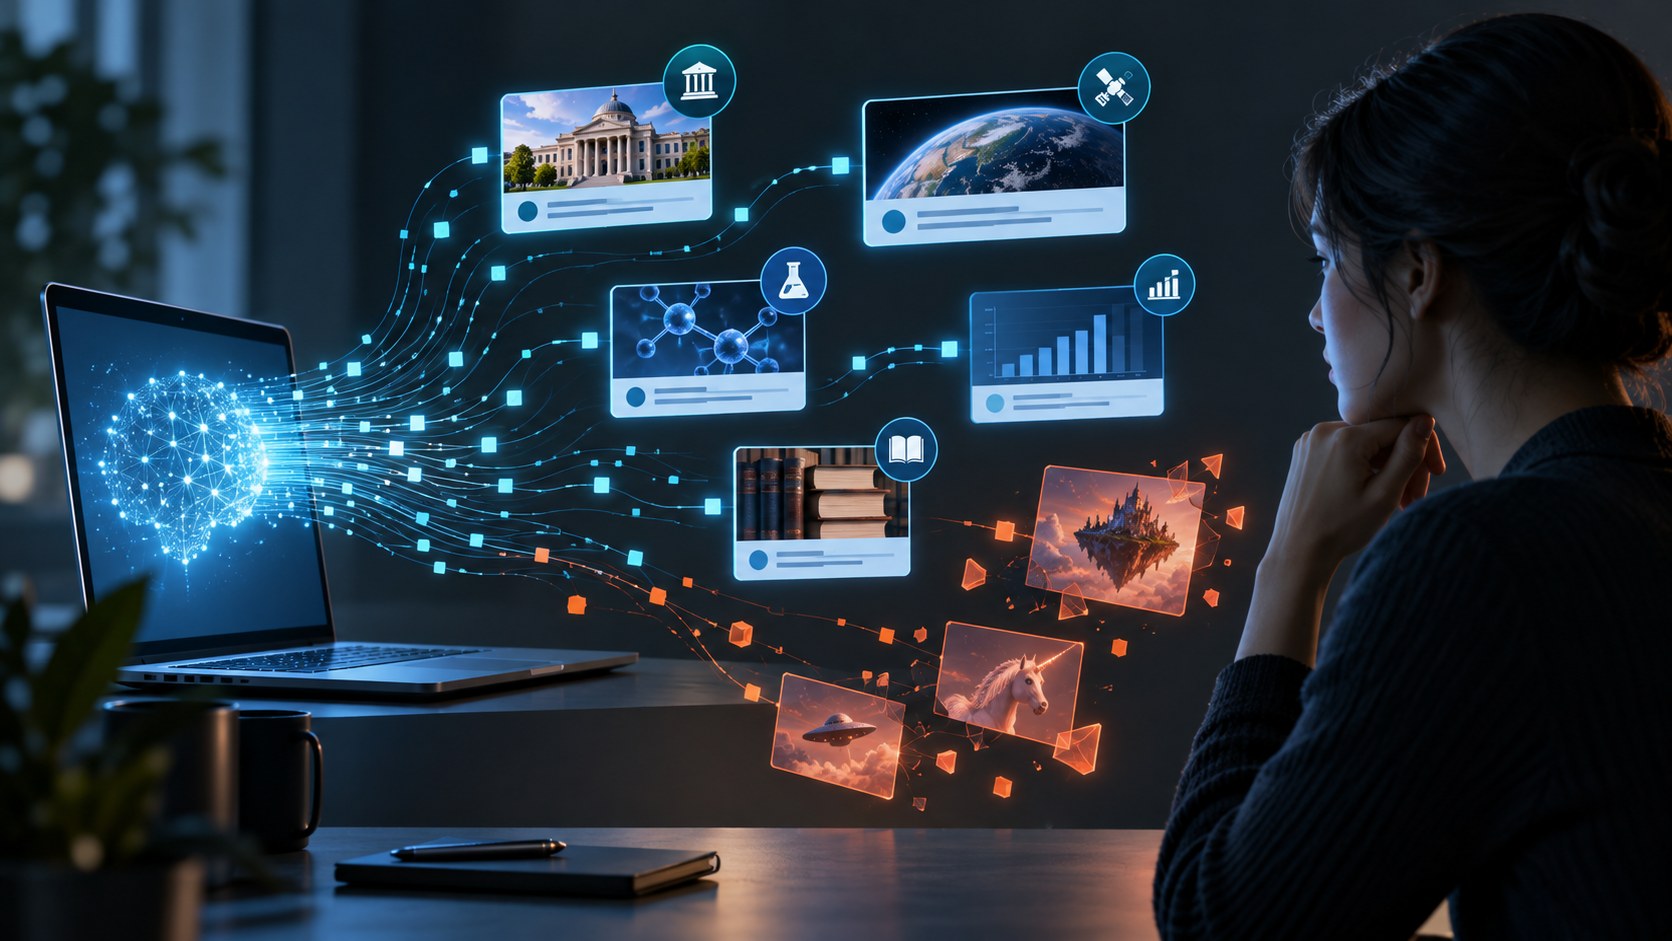
Large language models learn to predict the next token in a sequence. That training produces remarkably coherent language, but it does not automatically attach a truth label to every possible sentence. OpenAI’s research on why language models hallucinate argues that training and evaluation can also reward guessing when admitting uncertainty would receive no credit.
Prediction is not verification
The model chooses a likely continuation. It does not independently confirm every claim unless the system connects it to suitable evidence and checks that evidence.
Training data has gaps
Rare facts, new events, private information and specialized knowledge may be missing, inconsistent or weakly represented.
The prompt is ambiguous
Missing context can force the model to infer names, dates, goals or formats. A plausible assumption may become a confident false statement.
Context becomes noisy
Long conversations and large documents can contain conflicting details. The model may blend people, versions or sections together.
The request invites guessing
Asking for an exact quote, source or feature that may not exist can encourage the system to complete the expected pattern.
Retrieved sources can be weak
Web-connected tools may still use outdated, low-quality or irrelevant pages, then summarize them incorrectly.
More capable models often make fewer errors, but size alone does not guarantee factual reliability. Grounding, source quality, task design and evaluation all matter. Even an answer produced with web search should be checked at the linked page, because a system can misread a source or connect a citation to the wrong claim.
Common types of AI hallucinations
1. Factual hallucinations
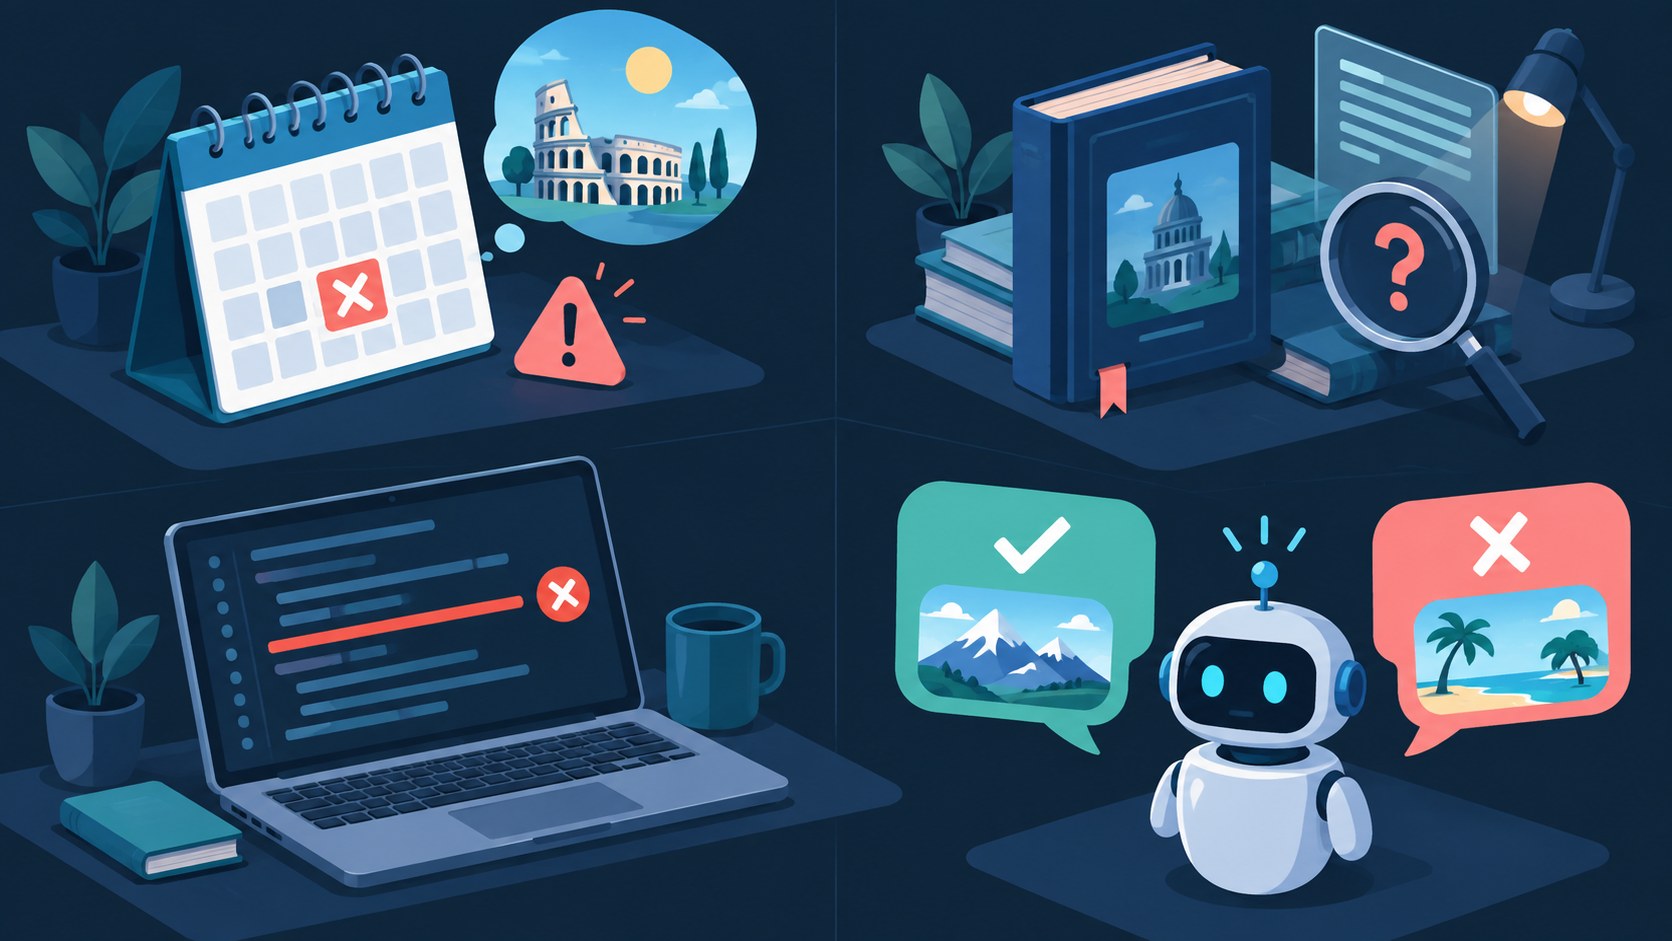
The model invents a date, event, person, statistic, location or relationship. These errors are especially hard to notice when the answer combines several true details with one false detail.
2. Fabricated citations and quotations
An answer may include a realistic article title, author list, journal name, URL or quotation that cannot be found. Never assume a reference exists because it is formatted correctly. Open the source, confirm the author and publication, and locate the claimed passage.
3. Contextual hallucinations
When asked to analyze a document, the model may add information from its general training or infer a claim the document does not support. This is a serious concern in contracts, policies, research papers and financial reports.
4. Consistency errors
A chatbot can contradict an earlier answer, change a number during a long conversation or silently switch assumptions. Repeating a question is useful for testing consistency, but two matching answers are still not proof.
5. Code and product hallucinations
AI coding tools can invent functions, command-line flags, package names or API parameters that look conventional. Test code in a safe environment and compare suggested features with official documentation. Our AI coding guide explains where model choice and verification matter.
6. Multimodal hallucinations
Image-aware models can misidentify an object, read text that is not present or describe a chart incorrectly. Generative image systems may create impossible anatomy, incorrect diagrams or misleading visual evidence. Audio and video tools can also add words, sounds or events that were never in the original material.
Warning signs that an AI answer may be wrong
No single clue proves a hallucination, but several patterns should trigger a closer check:
- The answer gives an exact statistic without naming a traceable source.
- A quotation is unusually perfect for the point being made.
- A cited URL is broken, redirects to an unrelated page or has a title that differs from the answer.
- The response claims that no exceptions exist in a complex legal, scientific or policy question.
- The chatbot changes dates, names or totals when asked again.
- A technical feature cannot be found in the current official documentation.
- The answer uses vague phrases such as “studies show” without identifying the studies.
- A summary contains facts that are absent from the uploaded document.
- The response remains confident after you point out conflicting evidence.
How to fact-check an AI answer
Verification does not require checking every ordinary sentence. Focus effort on claims that could change a decision: names, dates, numbers, quotations, medical or legal statements, financial assumptions, safety instructions, product compatibility and citations.
- Separate the claims. Break the answer into individual facts instead of trying to judge the whole paragraph at once.
- Mark the important ones. Prioritize details that affect cost, safety, rights, grades, publication or a production system.
- Ask for uncertainty. Request assumptions, missing information and parts of the answer the model is least certain about.
- Request sources. Ask for direct links, document titles, dates and page numbers. Treat them as leads until verified.
- Open the original material. Prefer official documentation, government publications, standards, peer-reviewed research and first-party announcements.
- Match each citation to its claim. A real source may not support the sentence placed beside it.
- Check dates and versions. Software, policies, prices and regulations change. Confirm that the source applies to the right time and region.
- Recalculate numbers. Inspect the inputs, units, formula and rounding rather than trusting a final total.
- Test technical output. Run code in a safe environment and consult the current official API or package documentation.
- Use qualified human review. Escalate high-stakes material to someone with the relevant professional expertise.
How to reduce AI hallucinations
You cannot guarantee that a chatbot will never hallucinate, but you can make unsupported guessing less likely. Good prompting helps because it defines the task, evidence and acceptable behavior. See our full guide on how to write effective AI prompts.
Give the model reliable context
Provide the relevant text, data or documentation and state that the answer must remain within it. If the task concerns a long file, identify the section or page range. Clean context is more useful than a large pile of loosely related material.
Allow the model to say “I don’t know”
Tell the system not to fill gaps with guesses. Ask it to flag missing information and distinguish facts from assumptions. This matters because a request that demands an answer can push a model toward a plausible completion.
Require claim-level citations
Ask for a source beside each important factual claim, then open every source. A bibliography at the end is less useful if you cannot tell which reference supports which sentence.
Use a structured prompt
Use only the information in the sources I provide.

For each factual claim:
1. Cite the exact source and section.
2. Separate confirmed facts from inferences.
3. State “not found in the provided sources” when evidence is missing.
4. Do not invent quotations, statistics, links or references.
5. End with a short list of claims that still need human verification.
Break complex work into stages
Ask the model to extract facts first, organize them second and draft the final response third. Review the extracted evidence before allowing it to become the basis of a conclusion. This is especially useful for the research workflow described in our guide to AI research tools.
Compare, but do not vote blindly
A second model can expose inconsistencies, yet two systems may repeat the same widely circulated error. Independent source verification is stronger than agreement between chatbots.
Reducing hallucination risk in organizations
Organizations need controls beyond a better prompt. The risk depends on the task. Brainstorming a slogan is different from summarizing a regulation, approving a refund or changing production infrastructure.
Risk-tier use cases
Classify tasks by potential harm. Require stricter evidence and approval for legal, medical, financial, safety and customer-facing output.
Ground answers in trusted data
Retrieval-augmented generation can supply current internal sources. Test whether the response is actually supported by what was retrieved.
Use review gates
Require a named person to approve high-impact content before it is sent, published or used by another automated system.
Test real failure cases
Build evaluations from the organization’s own ambiguous questions, missing documents, conflicting policies and past errors.
Log sources and versions
Record the model, prompt, retrieved material and reviewer so an answer can be reproduced and audited.
Limit automated actions
Do not let an unverified model output directly delete data, send money, change access or make a binding decision.
The risk becomes greater when AI agents pass outputs to one another. A fabricated detail from one step can become an accepted premise in the next. If you are designing automated workflows, read our introduction to AI agents and their risks.
IBM’s updated overview of AI hallucinations recommends measures that include better data, careful model selection, retrieval, structured prompts, monitoring and human oversight. The practical lesson is that reliability comes from the whole system around the model, not from a single instruction.
A quick checklist before you use an AI answer
- Can I identify every important factual claim?
- Did I open the original sources?
- Do the sources actually support the nearby claims?
- Are the dates, versions and region correct?
- Did I recalculate important numbers?
- Did I test code or technical steps safely?
- Does this require expert review?
- Am I keeping private data out of the prompt?
Students should also follow course rules and verify references before submission. Our AI for students guide covers responsible study and research habits. For privacy, account and data-handling precautions, use our AI chat safety checklist.
Frequently asked questions
What is an AI hallucination in simple terms?
It is an answer created by an AI system that sounds plausible but contains information that is false, invented or unsupported by the available source.
Why do chatbots make up facts?
Language models generate likely sequences of words from learned patterns. When evidence is missing, ambiguous or weak, a plausible continuation can replace a verified fact. Some training and evaluation methods can also reward guessing rather than uncertainty.
Can AI hallucinations be completely prevented?
No current general-purpose method guarantees perfect accuracy. Better models, grounded sources, retrieval, careful prompts, evaluations and human review can reduce the frequency and impact of errors.
Does web access stop hallucinations?
Web access can provide current evidence, but it does not guarantee that the sources are reliable or that the model interprets them correctly. Open the cited page and confirm the claim yourself.
How can I tell whether an AI citation is real?
Search the exact title, author and publication; open the original page; confirm the date or identifier; and find the passage that supports the claim. A real citation can still be attached to an unsupported statement.
Which AI tasks have the highest hallucination risk?
Risk is highest when a task depends on obscure facts, current events, missing private data, precise quotations, long or conflicting documents, specialized law or medicine, exact calculations, or undocumented software behavior.
Should I avoid generative AI because it can hallucinate?
No. Use it for suitable tasks with controls that match the consequences of an error. It can be effective for drafting, brainstorming, explaining and organizing, provided important output is verified before use.
Use AI as a capable assistant, not an unquestioned authority
AI hallucinations are easier to manage when you stop treating a polished answer as proof. Give the model strong context, make uncertainty acceptable, demand traceable evidence and keep a human responsible for consequential decisions.
The goal is not to distrust every generated sentence. It is to match the strength of your verification to the cost of being wrong.