Practical AI guide · 2026
What if an AI assistant could look up the right information before answering? That is the central idea behind retrieval-augmented generation, or RAG. This guide explains the workflow in plain language, shows where it helps, and makes its limits clear.
Editorial note: This is an educational explanation based on published research and product documentation, not a report of first-hand testing. AI systems and implementation details change. Verify important answers against the underlying sources and keep appropriate human oversight.
Imagine a customer asks a company chatbot, “Can I return this item after 30 days?” A general language model might offer a plausible answer based on common policies. A RAG system first searches the company’s current return policy, passes the relevant passage to the model, and asks it to answer from that evidence. The difference is simple: the answer is grounded in material selected for this question.
Key takeaways
- RAG combines retrieval and generation. It finds relevant content, then gives that content to a language model as context for an answer.
- It is useful for changing or private knowledge such as policies, manuals and internal documentation, provided the system has permission to use them.
- RAG is not automatic truth. It can retrieve the wrong passage, miss an update or produce an answer that overstates what the source says.
- Good RAG includes source visibility and testing. People should be able to inspect the underlying document, date and exact claim when accuracy matters.
What is retrieval-augmented generation (RAG)?
Retrieval-augmented generation is an approach that connects a generative AI model to an external collection of information. When a user asks a question, a retrieval system looks for relevant material. The model then receives that material with the question and generates a response.
The name describes its three parts: retrieval finds useful passages, augmentation adds them to the model’s prompt, and generation produces the answer. The influential 2020 RAG research paper by Lewis and colleagues combined a language generator with a retrievable external memory. Today, “RAG” commonly describes a wider family of source-grounded application designs.
The external information may be public web pages, product manuals, approved company files, policy documents or a research library. It does not have to be a vector database: search can use keywords, semantic matching or both. The right method depends on the content and the question.
For a broader introduction to the underlying models, see our guide to generative AI. RAG is one way to give a generative model relevant information at the moment it answers.
How does RAG work? A five-step workflow
Different products vary, but a typical system follows this path. IBM’s updated RAG overview and Microsoft’s RAG documentation describe the same core idea: search supplies context that helps ground the model’s response.
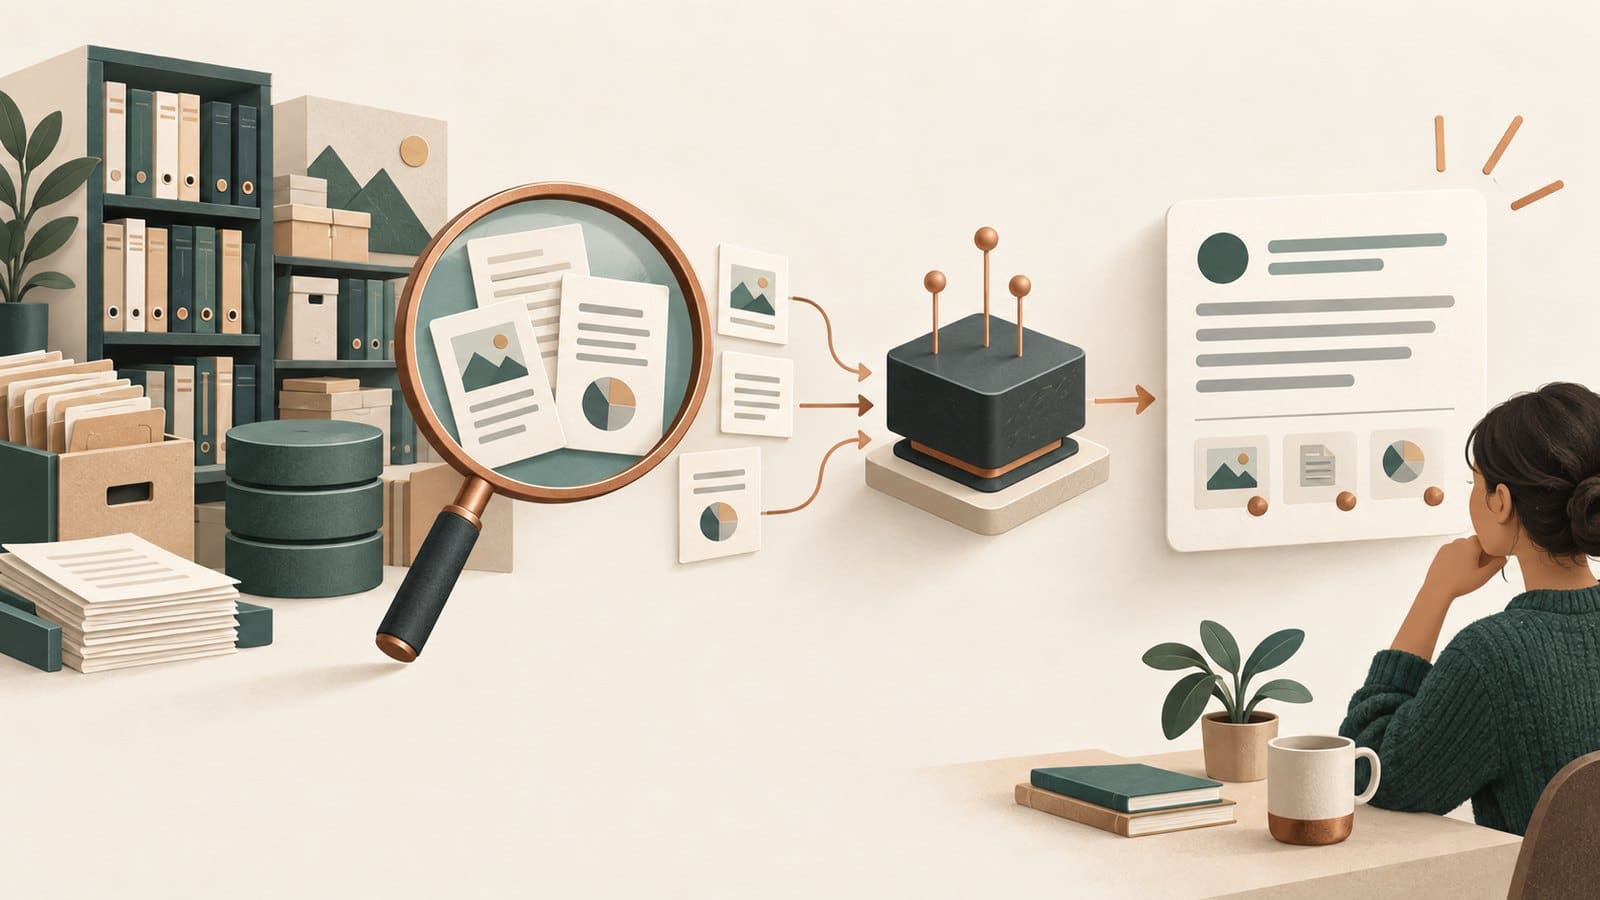
- Prepare the knowledge source. Collect approved documents, remove duplicates, preserve titles and dates, and make the material searchable. Longer files are often divided into passages so a search can find the useful part.
- Ask a question. A user asks, for example, “What is our refund window for digital purchases?”
- Retrieve relevant passages. The search layer finds candidate passages. Some systems combine keyword search with meaning-based search and rerank the results.
- Generate a grounded answer. The application passes the selected passages and clear instructions to the model, such as “Answer only from these sources; say when evidence is missing.”
- Show evidence and check the result. The response can link to its source passages. A stronger workflow also checks whether the answer is actually supported and whether the source is current.
A useful mental model is an open-book answer: the model still writes the response, but it has been given specific pages to consult. “Open-book” does not mean the pages are correct or that the model reads them perfectly.
A concrete RAG example
Suppose a small online store changes its shipping policy from “3–5 business days” to “5–7 business days.” A standalone model may still repeat the older figure or invent a generic estimate. A RAG-powered support assistant can search the updated policy and respond:
“The current standard delivery estimate is 5–7 business days after dispatch. See the shipping policy, updated September 2026.”
That response is only as good as the retrieval. If the old policy remains in the index, the assistant may find the wrong version. If the policy lists different times by region, it must ask where the customer is located or state the condition. Version control, clear document ownership and citations are as important as the model.
This pattern also applies to an employee finding a benefit policy, a technician locating a troubleshooting step or a researcher searching a collection of papers. Our AI chatbot for business guide covers the broader decisions around customer support, human handoff and protecting sensitive information.
Where RAG helps most
RAG is especially useful when the answer lives in a defined set of material and users need to see where it came from. Examples include:
- Customer support: find the correct current policy or product instruction before drafting a reply.
- Internal knowledge search: answer an employee’s question from approved handbooks and procedures, with access limited to what that employee may see.
- Technical documentation: locate a relevant manual section, software version or troubleshooting step.
- Research assistance: summarize a controlled set of papers or reports while linking back to the original passages.
- Compliance preparation: find relevant written requirements for a human reviewer. The system should not replace qualified advice or final approval.
RAG also makes updates easier in one narrow sense: a team can revise the searchable knowledge source instead of retraining the underlying language model for every policy change. That does not mean updates appear instantly. The index still has to refresh, old copies may need removal, and the application must retrieve the right version.
RAG vs a normal chatbot, long context and fine-tuning
These methods solve different problems. They can complement one another.
| Approach | How it uses knowledge | Good fit | Main caution |
|---|---|---|---|
| General chatbot | Answers mainly from its training and the current conversation | Brainstorming, writing, general explanation | May not know your latest or private facts |
| Long-context prompt | Reads files or text directly included in the prompt | A few known documents for one task | Large inputs can be slow, costly or hard to navigate |
| RAG | Searches a source collection for relevant passages before answering | Repeated questions over many changing documents | Search and source quality can fail |
| Fine-tuning | Adjusts a model using training examples | Teaching a consistent output style, format or specialized behavior | Not a simple way to keep changing facts current |
If you have one short PDF, placing it directly in a prompt may be enough. If hundreds of policies change every month, retrieval becomes more attractive. Fine-tuning can help a model follow a style or task pattern, but it is usually a poor substitute for fetching a current policy. Microsoft’s RAG introduction explains how external sources can supply knowledge without retraining the model.
RAG can also work alongside AI agents: an agent might decide when to search a knowledge base, then use retrieved evidence to plan its next step. The retrieval component supplies information; the agent’s tools and permissions determine what it can do with that information.
What RAG does not fix
RAG often improves the relevance and traceability of an answer, but it is not a guarantee. IBM explicitly notes that grounding can lower hallucination risk without making a model error-proof. Common failure points include:
- Wrong retrieval: the search picks a similar but unrelated passage.
- Missing material: the needed document was never indexed, or the scan lost text.
- Outdated material: an old policy ranks above the current one.
- Weak synthesis: the model mixes two sources, ignores a condition or cites a passage that does not support its claim.
- Unsafe access: the search returns information the user is not authorized to see.
- Malicious source content: a retrieved page contains instructions intended to redirect the assistant rather than facts for the user’s question.
For more on confidently stated but unsupported AI claims, see our AI hallucinations guide. Its verification advice still applies when a system supplies citations.
Important distinction: a citation shows where a system found text. It does not prove that the source is authoritative, current, or correctly interpreted. Open the cited passage when the answer matters.
A practical checklist for using or building RAG
You do not need to start with a complex architecture. Begin with one narrow question type and a trusted document set.
- Define the job. Decide what questions the assistant should answer and which ones require a person.
- Choose approved sources. Give every document an owner, date, version and access rules.
- Test retrieval before generation. For sample questions, inspect whether search returns the correct passage near the top.
- Require uncertainty. Tell the assistant to say when the sources do not answer the question instead of filling gaps.
- Show exact sources. Link users to the document or passage, not merely a vague document title.
- Evaluate with real questions. Include normal, ambiguous, outdated and adversarial questions, then review errors with a human.
- Maintain the library. Remove superseded files, refresh the index and repeat tests after updates.
A useful evaluation question: “Our policy changed last week. Does the assistant cite the new version, state the correct condition, and decline to answer if the relevant page is missing?”
That single question tests source freshness, retrieval quality, answer support and uncertainty more meaningfully than asking whether the response sounds fluent.
Frequently asked questions
Does RAG train the AI on my documents?
Usually, no. In a typical RAG workflow, documents are indexed for search and relevant passages are supplied at answer time. This is different from updating model weights through training. Always check a provider’s specific data-handling policy before uploading private material.
Does RAG require a vector database?
No. Semantic vector search is common, but keyword search or a hybrid of keyword and semantic retrieval can also support RAG. A small, well-structured collection may not need a specialized vector database.
Can RAG prevent hallucinations?
It can reduce some unsupported answers by providing relevant evidence, but it cannot eliminate them. Retrieval may fail, sources may be wrong, and the model may misread them. Citations and human verification remain important.
When is RAG unnecessary?
If the task is general brainstorming, rewriting a paragraph or answering from a short document already in the prompt, a retrieval system may add complexity without enough benefit. Use RAG when repeated questions require a searchable, changing source collection.
Is web search the same as RAG?
Web search can serve as the retrieval step in a RAG-style workflow, but a RAG system may instead search an internal document set or another controlled repository. The defining pattern is retrieving relevant information and using it to ground a generated answer.