A large AI model can answer difficult questions, but running it for every routine task may be slow and expensive. AI model distillation trains a smaller “student” model to learn useful behavior from a stronger “teacher” model. The result can be a faster, cheaper model for a specific job—if the training data, permissions and evaluation are handled well.
The topic has become more visible in 2026 because AI companies are also reporting unauthorized attempts to copy model capabilities at scale. This guide separates normal, permitted distillation from those attacks and explains what the technique actually does.
Last reviewed: October 4, 2026.
What Is AI Model Distillation?
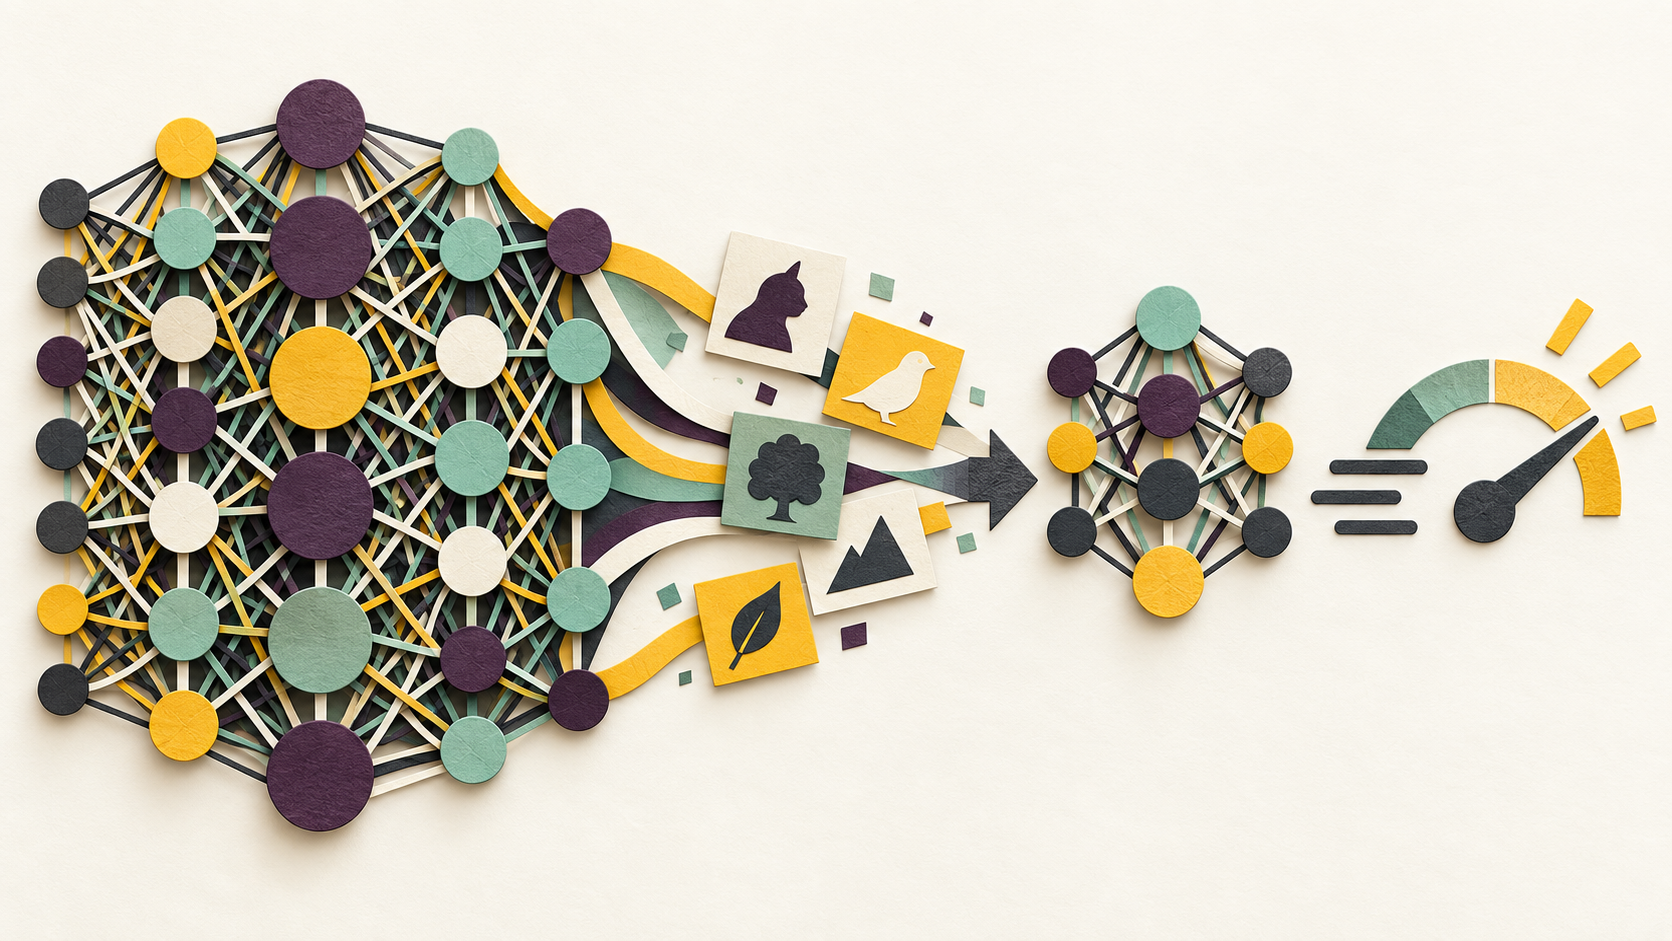
Model distillation is a training method in which a smaller model learns from the outputs or guidance of a larger model. The teacher processes examples and produces answers, scores or probability distributions. The student then learns to produce useful results without needing the teacher at every future request.
Imagine an expert tutor showing a student how to classify support requests. The tutor handles many examples and explains what a good answer looks like. After practice, the student can handle familiar cases independently. The analogy is imperfect—models learn patterns rather than understanding lessons as people do—but it captures the teacher–student relationship.
Distillation is a subset of model optimization, not a new kind of generative AI. It can be combined with other techniques such as quantization, pruning and fine-tuning, which change a model in different ways.
How Does Distillation Work?
1. Choose a task and a teacher
A team first defines the job the student should do: summarize short documents, classify requests, answer questions in a domain or make routine decisions in an agent workflow. It chooses a teacher model that performs that job well enough to supply useful examples. A strong teacher is only valuable when its output is accurate, relevant and permitted for training.
2. Build a representative dataset
The team gathers prompts or inputs that resemble real work. If the student will answer customer questions, the examples should cover common questions, unusual edge cases, different writing styles and safe ways to decline unsupported requests. Private information should be removed or handled under appropriate permissions.
3. Generate teaching signals
The teacher can provide final answers, rankings, labels or richer probability signals. In a simple workflow, the dataset contains a prompt and a high-quality teacher response. More advanced methods may compare several candidate responses or use scores that convey how the teacher distinguishes good and bad outcomes.
4. Train and test the student
The smaller model trains on the examples, then is tested on fresh tasks it did not see during training. Evaluation should measure task quality, latency, cost and failures. If the student only memorizes examples, it may look strong in a demo but fail on new inputs.
- Accuracy: Does the student complete the target task correctly?
- Speed: Is response time better under real traffic?
- Cost: Does the smaller model reduce total operating cost after training?
- Safety: Does it preserve necessary refusals, privacy controls and reliability?
- Coverage: Which cases still require the larger model or human review?
Why Make a Smaller Student Model?
The main reason is efficiency. A specialized model may answer common requests with less computing power, lower latency and more predictable costs. Smaller models can also fit environments where a frontier model is impractical, such as a local device or a high-volume service.
The trade-off is capability. A student may imitate the teacher well on a narrow task while performing worse on unfamiliar questions, long reasoning chains or subtle safety decisions. Distillation should be judged against the workload it will actually serve, not against a broad claim that a small model is “as good as” a large one.
This matters for AI agents: a simple routing or classification step may be suitable for a small model, while a complex plan or consequential decision may need a stronger model and human oversight.
Distillation vs Fine-Tuning, Quantization and RAG
| Method | What changes | Typical goal |
|---|---|---|
| Distillation | A student model learns from a teacher’s outputs or signals. | Transfer useful behavior into a smaller model. |
| Fine-tuning | An existing model is trained on selected examples. | Adapt behavior, format or domain performance. |
| Quantization | Model numbers use lower precision. | Reduce memory and compute needs. |
| Retrieval-augmented generation | The model retrieves external information at answer time. | Ground answers in current or private sources. |
These methods can work together. A team might distill a model for common questions, quantize it for cheaper deployment and use retrieval-augmented generation when answers require up-to-date documents. The right combination depends on measured quality and cost.
When Is Distillation Legitimate?
Distillation is a normal research and product-development technique when the team has permission to use the teacher and its outputs for training. A company may distill its own model. An AI provider may offer a documented distillation service. A researcher may use a model under a license that permits the planned use.
OpenAI’s model distillation API announcement describes a developer workflow for creating smaller task-specific models using its services. The permission to generate an answer for ordinary use does not automatically mean permission to collect millions of answers to train a competing model; current terms and licensing need to be checked.
What Is an Illicit Distillation Attack?
An illicit distillation attack is a coordinated attempt to extract a model’s capabilities without authorization. Attackers may use large numbers of accounts, repeated task patterns or automated pipelines to collect responses for training another model. Some campaigns target valuable abilities such as coding, tool use or reasoning.
Anthropic reported in February 2026 that it had identified large-scale campaigns against Claude. Its later September 2026 threat report described additional activity and differentiated ordinary teacher–student training from covert extraction. These are the company’s reported findings; readers should treat attribution and scale as claims from the reporting provider.
Why does the distinction matter? Unauthorized extraction can breach service terms, undermine safety controls and raise privacy concerns if real user conversations are collected. But calling every smaller model a “stolen” model would be inaccurate. The legality and ethics depend on the source of the data, the provider’s terms, the training workflow and the specific conduct.
Can a Distilled Model Be as Good as Its Teacher?
Sometimes it can match or even exceed a teacher on a narrow benchmark if the student is optimized for that task and evaluated fairly. That does not mean it has copied all of the teacher’s general ability. A student trained on customer support examples may be excellent at routing tickets but weak at unfamiliar scientific questions.
It is also possible to inherit the teacher’s errors. If generated examples contain wrong facts, hidden bias or unsafe advice, the student can absorb those patterns. A careful pipeline filters examples, samples diverse cases and tests against independently labeled data.
A Practical Checklist for Teams
- Define the exact task and decide whether a smaller model is truly needed.
- Confirm that the teacher model, generated outputs and training data may be used for this purpose.
- Remove unnecessary personal or confidential information from examples.
- Measure the teacher’s error rate before using its answers as labels.
- Train on varied cases and reserve separate examples for final evaluation.
- Compare quality, latency, total cost and safety against the current system.
- Route uncertain or high-impact cases to a stronger model or human reviewer.
For most website owners or small teams, building a distilled model from scratch is unnecessary. Start by selecting an appropriate existing model and measuring where it fails. Distillation becomes useful when a stable, repeated workload justifies the training effort.
Frequently Asked Questions
Is model distillation the same as copying a model?
No. It normally trains a separate student on teacher-generated examples or signals rather than copying the teacher’s weights. Whether a particular workflow is authorized is a separate question.
Does a smaller model always cost less?
Inference may cost less, but training, evaluation, hosting and monitoring also cost money. Compare the total cost for the expected workload.
Can distillation preserve safety rules?
It can transfer some safe behavior, but safeguards must be tested directly. A student may fail in cases the teacher handles correctly.
Can nontechnical users benefit from distillation?
Yes, indirectly. Many products use smaller specialized models to improve speed and availability. Users do not need to train the model themselves to benefit.
Final Thoughts
AI model distillation helps make useful AI behavior smaller and more efficient. The method works best when the target task is clear, the teacher data is permitted, and the student is tested on real cases. Recent reports of illicit extraction make the permission and security questions more visible, but they do not change the value of legitimate distillation.
If you are choosing models for a workflow, begin with a simple quality and cost comparison. Our guides to AI agents and RAG explain two common ways those models are used.
Sources: OpenAI model distillation; Anthropic distillation disclosure; Anthropic September 2026 threat report.