When you ask an AI chatbot a question and it writes a response, the system is performing AI inference. It is using a trained model to process your input and produce an output. Training builds the model; inference puts that model to work.
Inference also happens when an image generator creates a picture, a speech system transcribes audio, or an AI agent decides which tool to use next. Understanding it helps explain why one AI response arrives instantly while another takes longer, why prices vary, and why smaller models can sometimes be the better choice.
Last reviewed: October 4, 2026.
What Is AI Inference?
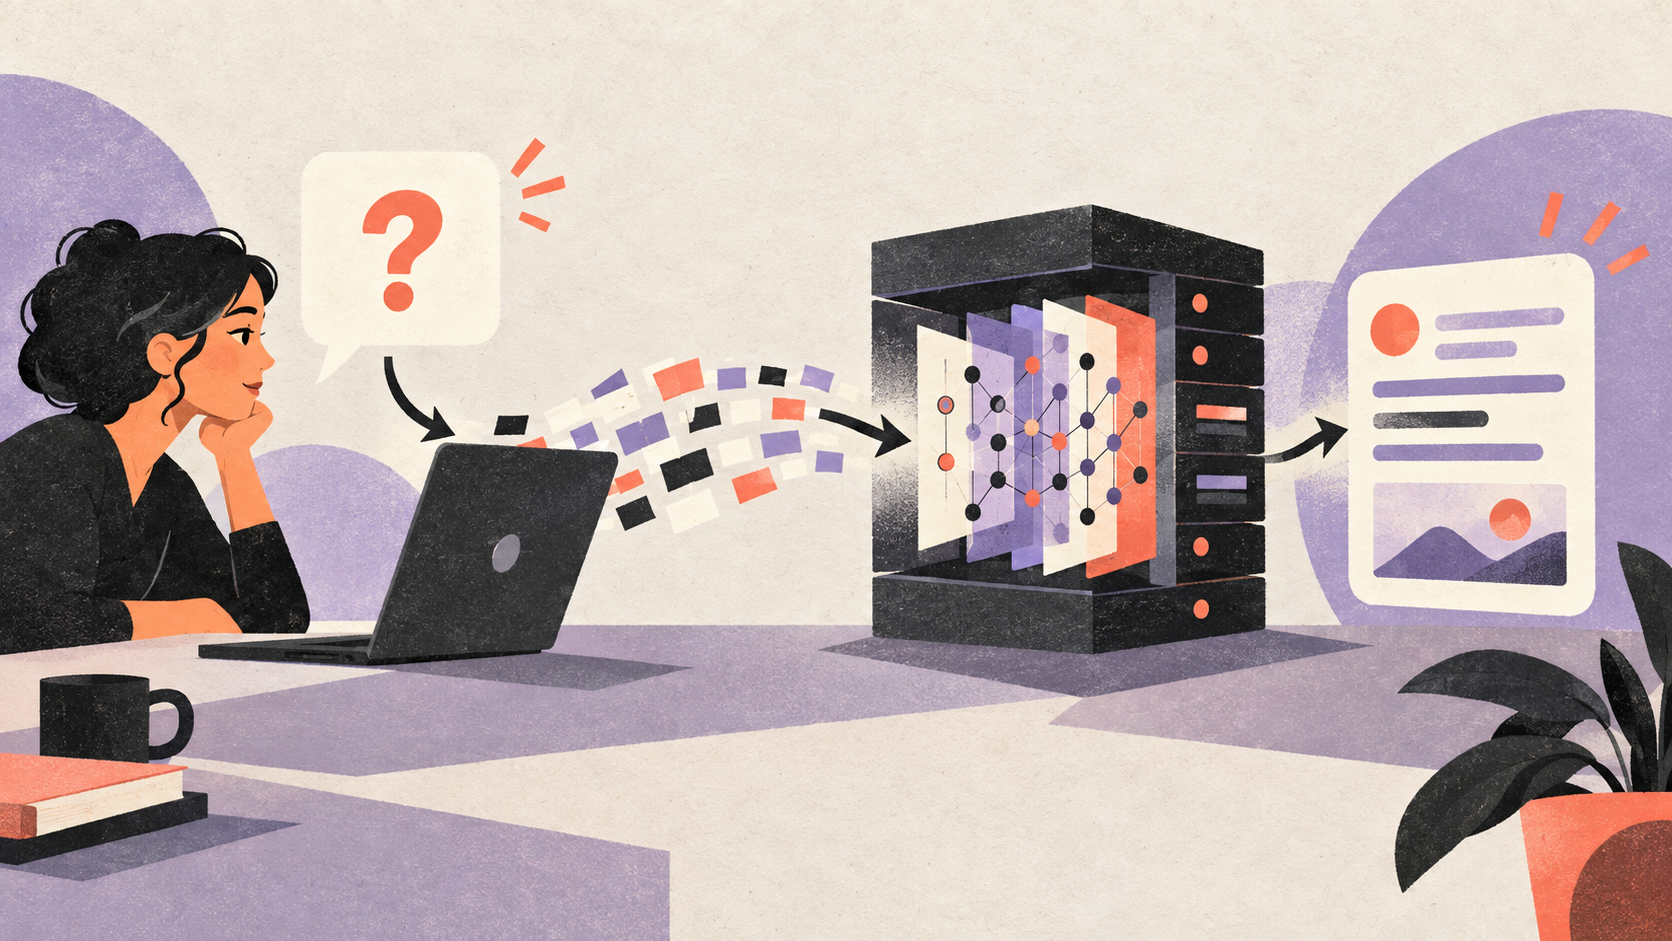
AI inference is the process of running a trained model on new input to make a prediction or generate an output. For a language model, the input may be your message plus instructions and previous conversation. The output is a sequence of generated tokens that becomes readable text. For an image model, the input may be a prompt and a reference image, while the output is a newly generated image.
The name can sound technical, but the everyday experience is familiar: you ask, the system responds. The hidden work includes reading the input, choosing a model, allocating computing resources, calculating the next output and sending the result back to you.
NVIDIA’s AI inference explanation describes the relationship between prompt processing, token generation, speed and cost. The details vary by model architecture, but the distinction between training and using a trained model applies broadly.
AI Training vs AI Inference
| Question | Training | Inference |
|---|---|---|
| What happens? | The model’s parameters are learned or updated from data. | A trained model processes a new request and produces an output. |
| When? | Before or between model releases, or during later fine-tuning. | Whenever a user or application calls the model. |
| Example | Learning language patterns from a large dataset. | Answering “Summarize this page” in a chat. |
| Main concern | Training data, compute, evaluation and alignment. | Latency, cost, reliability, privacy and user experience. |
Training can be expensive and lengthy, but inference is repeated across every user request. A popular service may perform inference millions of times a day. That recurring workload is why providers invest heavily in serving software, chips, caching and model selection.
How Does an AI Inference Request Work?
1. The application receives your input
Your message arrives with other context the application may add: system instructions, conversation history, retrieved documents or tool results. A long input can require more processing than a short one. An AI agent may add even more context as it works through several steps.
2. The system prepares tokens
A text model does not read words exactly as a person does. It converts input into tokens, which may represent words, word parts or other units. The amount of input affects processing time and, for usage-based services, often the bill.
3. The model computes an output
The model processes the input and predicts a useful continuation. Many chat systems generate output token by token. A reasoning-focused model may spend additional computation before presenting its answer, while a simpler model may respond faster.
4. The application returns and checks the result
The service streams or sends the answer back. It may apply safety checks, formatting, retrieval or tool calls along the way. A visible reply is therefore the result of both model inference and the surrounding application workflow.
Why Do Some AI Answers Take Longer?
The first reason is the size and complexity of the request. A long document takes more work to read than a short question. A request for a long answer takes more output steps. Images, audio and video can add different processing demands.
The second reason is model and system design. A larger model, a model using more reasoning steps, or an agent calling several tools may take longer. Server load, network travel and how quickly hardware becomes available also affect the delay you feel.
Providers measure this in several ways. Time to first token captures how quickly the first part of a reply appears. Output speed measures how fast the rest arrives. End-to-end latency includes the full workflow. For a user, a system that starts quickly but finishes slowly may feel different from one that pauses and then delivers the full answer at once.
What Determines AI Inference Cost?
- Input size: Longer prompts and attached context require more processing.
- Output size: A long answer generally uses more generation work.
- Model choice: More capable models can require more resources per request.
- Hardware and utilization: Idle capacity, memory, networking and power all affect cost.
- Serving software: Batching, caching and scheduling can improve efficiency.
- Extra steps: Tool calls, retrieval, safety checks and repeated attempts add work.
NVIDIA’s infrastructure discussion notes that cost per request depends on more than chip purchase price; throughput, software, networking and energy all matter. OpenAI’s infrastructure overview similarly describes chips, serving software and networking as connected parts of inference performance.
A price per million tokens is useful, but it is not the entire cost of a product. A model that is cheap per token may need more retries or longer prompts. A more expensive model may solve a difficult task in fewer steps. Compare successful outcomes per dollar, not just list prices.
What Is the Difference Between Prefill and Decode?
Some language-model serving systems divide work into two phases. Prefill processes the input prompt and builds the internal state needed to answer. Decode generates the response, often one token at a time. A very long prompt can make prefill expensive, while a very long answer can make decode the dominant part of the experience.
This distinction helps explain why faster AI has more than one meaning. A service can improve the time before an answer begins, the speed of ongoing generation, or the number of users it serves at once. Hardware and software choices may improve one measure more than another.
AI Inference Across Text, Images, Audio and Video
Text chat is only one form. An image model performs inference when it creates or edits a picture from a prompt. A speech model performs inference when it transcribes spoken words or generates a voice. Video generation processes frames and motion over time, which can be especially compute-intensive.
On Unlimited AI, people can explore chat, image, music and video tools. The interface may feel unified, but each tool can use a different model and processing path. That is why speed, limits and output quality can differ across tasks.
How Can Teams Make Inference Faster and More Affordable?
Choose the smallest model that reliably solves the task
A smaller model may be enough for classification, routing or a simple summary. Reserve a stronger model for complex reasoning, ambiguous cases or high-stakes review. The choice should be based on tests with real tasks rather than model size alone.
Reduce unnecessary context
Sending an entire document library with every request wastes processing and can distract the model. Retrieve only relevant material, summarize long history when appropriate, and remove repeated instructions. Our context engineering guide explains how to select useful information for an AI workflow.
Cache and reuse safe results
If many users ask the same stable question, an application may reuse an approved answer or cache part of the prompt. This can lower latency and cost. Caching needs care when answers depend on private data, recent events or changing account state.
Measure the whole workflow
Track how often a request succeeds, how long it takes, how many tokens it consumes and when a human must correct it. An agent that calls a model five times can cost more than a single answer even when each call is cheap.
What Does Inference Mean for AI Agents?
AI agents often make several model calls in one task: interpret a goal, decide on a tool, inspect the tool result, revise a plan and prepare a final response. Each call is another inference step. This can improve results on complex tasks but increases latency, cost and the need for safeguards.
A sensible workflow uses a simple model or deterministic rule where the decision is easy, then escalates uncertain cases. Human approval remains important when the agent could send information, change records or take other consequential actions.
Does Faster Inference Mean Better AI?
No. Fast responses are valuable, but speed does not guarantee accuracy. A system can answer quickly and still misunderstand the question, invent a source or skip a necessary check. For important work, compare accuracy, citations, privacy and reliability alongside speed.
Our AI hallucinations guide explains why fluent output can be wrong. Inference optimization should preserve the checks that help users notice and correct those errors.
Frequently Asked Questions
Is AI inference the same as an AI prediction?
Prediction is one common output of inference. In generative AI, inference may produce text, images, audio, video or actions rather than a single category or number.
Does every chatbot message start a new inference request?
Usually, yes. The application may include earlier conversation as context, but the model still processes the current request to generate the next response.
Why are input and output tokens priced differently?
They can require different amounts of computation and serving capacity. The exact pricing method depends on the provider and model, so check current documentation.
Can AI inference happen on a phone?
Yes. Some smaller models run locally on phones and computers. Other applications send requests to cloud servers. The choice affects speed, privacy, battery use and available model capability.
Final Thoughts
AI inference is the moment a trained model becomes useful to a person or application. It turns a prompt, image or sound into an answer, prediction or generated asset. The practical questions are how quickly it works, what each successful result costs and whether the output is trustworthy enough for the task.
As AI products become more complex, the best experience will come from choosing the right model, sending the right context and checking outcomes, rather than simply using the largest model for every request.
Sources: NVIDIA: AI inference; NVIDIA: inference cost factors; OpenAI: inference infrastructure; Google Cloud: measuring inference impact.