Beginner-friendly guide · 2026
Multimodal AI is artificial intelligence that can understand or create more than one type of information, such as text, images, audio, video and documents. Instead of forcing every task into a text box, a multimodal system can examine the media that carries the most useful evidence.
That matters because real questions rarely arrive in one format. A student may have a photographed diagram and a written question. A business may need to compare a PDF, a product image and a recorded meeting. A creator may start with a script, reference picture and audio track. Multimodal AI connects those inputs in one workflow.
What is multimodal AI?
A modality is a way information is represented. Written language is one modality; photographs, speech, music, video and structured data are others. A multimodal AI model can process two or more of them and connect their meaning.
For example, you could upload a chart and ask a question in natural language. The system must identify visual elements, understand the written request and produce a useful response. A more advanced workflow might listen to spoken instructions, inspect a live camera view and respond with speech.
This is broader than ordinary generative AI. A text-only generator creates text from text. A multimodal generator can accept or produce several media types, although each product supports a different combination.
How does multimodal AI work?
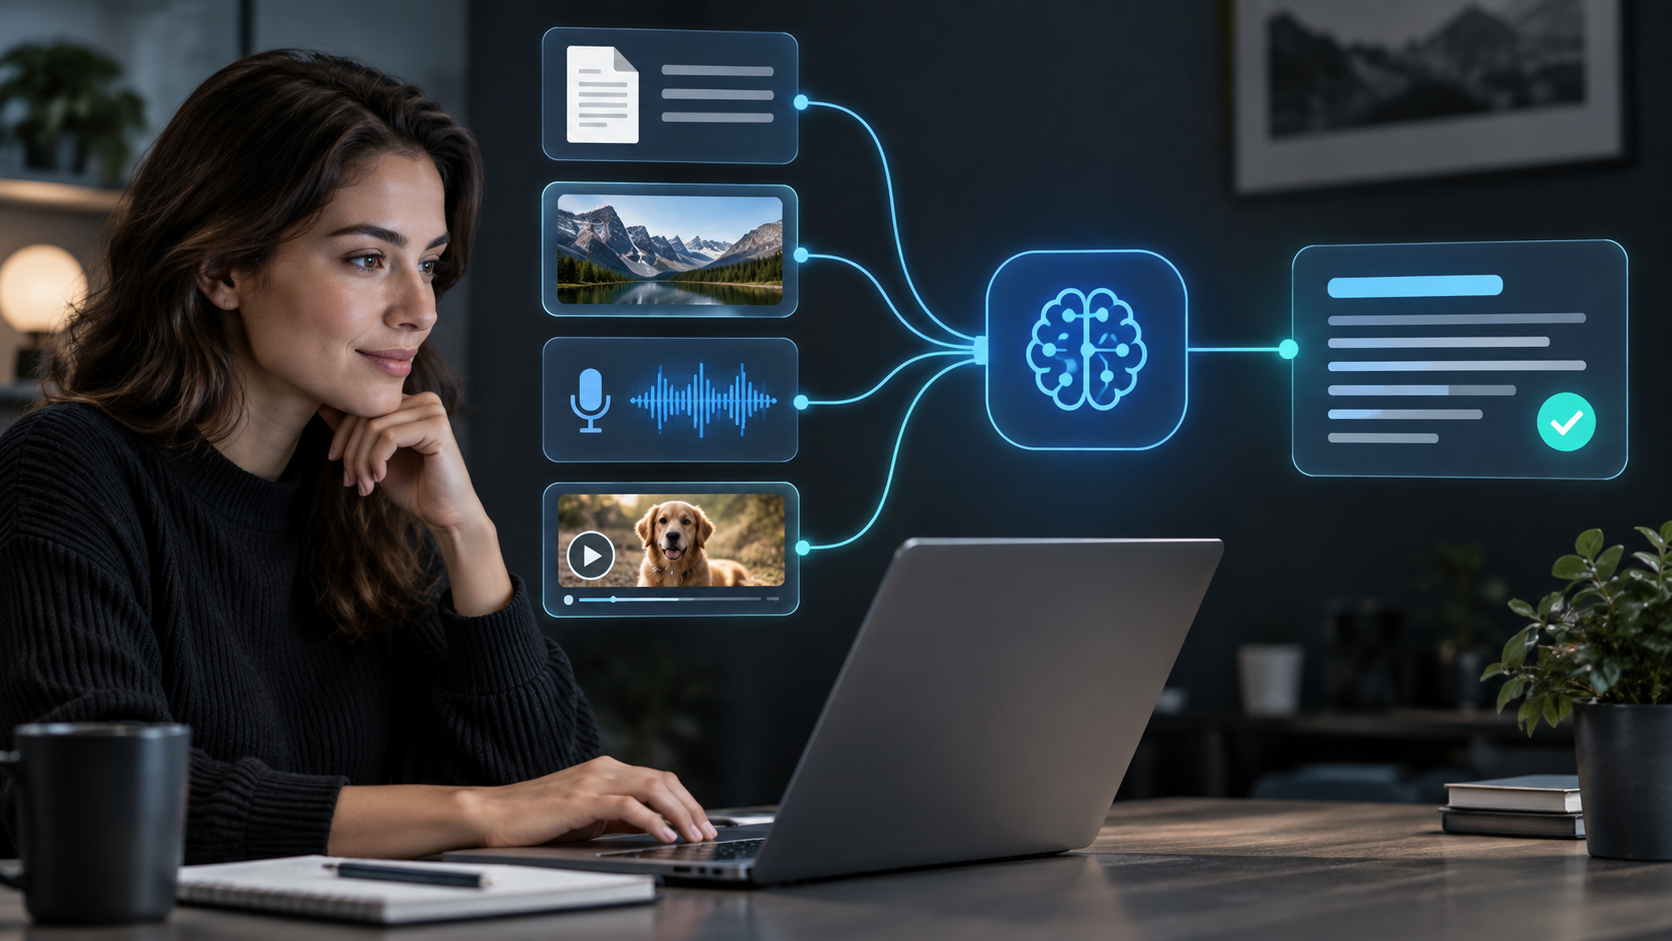
At a high level, the system first converts each input into a machine-readable representation. An image encoder identifies visual patterns. A speech system converts sound into tokens or audio features. A language model processes words and instructions. The system then aligns relevant parts so it can reason across them.
1. The system receives one or more inputs
Inputs might include a prompt, screenshot, photograph, PDF, spreadsheet, voice recording or video. The tool may impose limits on file size, length, resolution and supported formats.
2. Specialized components interpret each format
Different encoders detect useful structure: objects and text in an image, speakers and words in audio, frames and movement in video, or headings and tables in a document. The system does not experience these inputs like a person; it maps patterns into numerical representations.
3. The model connects information across formats
Cross-modal alignment lets the model relate “the red line” in a written question to the red line in a chart, or connect a spoken comment to a particular moment in a video. This connection is the key advantage over separate tools that never share context.
4. It generates or retrieves an output
The answer might be text, an edited image, a spoken response, code, a summary or a new video. Some systems can also call search and other tools, so users should distinguish model inference from verified external evidence.
Multimodal AI vs generative AI vs conversational AI
| Term | Main idea | Example |
|---|---|---|
| Multimodal AI | Understands or generates multiple information formats | Ask questions about a photo and receive a text answer |
| Generative AI | Creates new content from learned patterns | Generate an article, image, song or video |
| Conversational AI | Interacts through natural-language dialogue | A chatbot that remembers the current conversation |
| Computer vision | Analyzes images or video | Recognize objects in a photograph |
These categories overlap. A conversational assistant can be multimodal and generative at the same time. Our conversational AI guide explains the dialogue layer in more detail.
Common multimodal AI inputs and outputs
- Text: prompts, articles, code, captions and structured instructions.
- Images: photos, screenshots, diagrams, scanned pages and design references.
- Documents: PDFs, reports, presentations, spreadsheets and forms.
- Audio: speech, interviews, sound effects and music.
- Video: frames, movement, scenes, subtitles and sound.
- Tool results: web search, databases, calculators or connected applications.
A tool described as multimodal may support only text and images, while another may add live audio or video. Check both input and output capabilities. The ability to inspect a video does not automatically mean the system can generate one.
Practical multimodal AI use cases
Understand screenshots and visual problems
A user can share an error message, dashboard or interface and ask for an explanation. The screenshot provides details that would be slow to type, while the text prompt clarifies the desired outcome. Remove account numbers, private conversations and security credentials before uploading.
Analyze documents with charts and tables
A multimodal system can summarize paragraphs while also interpreting a chart or scanned table. This is useful for research, but every quotation, number and citation should be checked against the original page.
Create images and video from a brief
Creators can combine a written concept with a visual reference, brand colors or composition notes. The Unlimited AI Image Generator turns text prompts into images, while the Unlimited AI Video Generator supports video creation workflows.
Transcribe and organize audio
Speech can be converted into text, summarized and organized into action items. Speaker names, dates and commitments require human confirmation, especially when audio quality is poor or several people talk at once.
Improve accessibility
Multimodal tools can describe images, generate captions, read text aloud or translate speech. Useful output still needs review because an inaccurate description or missing caption can create a new accessibility barrier.
Why multimodal AI is trending in 2026
Search behavior itself is becoming multimodal. In September 2026, Google announced multimodal Search performance reporting in Search Console for discovery through Lens, Circle to Search, image uploads and related visual-search experiences.
Google has also reported that more than one in six AI Mode searches use voice, images or video. This reflects a practical shift: people increasingly show an AI system what they mean instead of describing everything with keywords.
The trend is also visible in developer platforms. The OpenAI multimodal cookbook groups current work across vision, images and speech, while Google Cloud describes systems that process images, video and text.
Benefits of multimodal AI
- More context: the model can use details that are difficult to express in words.
- Faster workflows: users can share an existing file instead of manually converting it into text.
- Better interfaces: people can type, speak, point, upload or combine methods.
- Creative flexibility: text, images, sound and video can become parts of one production process.
- Stronger document understanding: layout, charts and visuals can be considered with written content.
Limitations and risks
More inputs create more opportunities for error. A model may read text in an image incorrectly, miss a quiet speaker, misunderstand a chart legend or focus on the wrong video frame. A fluent answer can hide those mistakes.
- Hallucinations: the system may invent details not present in the source.
- Privacy: uploaded files may contain faces, locations, signatures or confidential data.
- Bias: performance can vary across accents, languages, cultures and visual conditions.
- Copyright and consent: reference media may not be licensed for reuse or generation.
- Security: documents and images can contain malicious or misleading instructions.
- Cost and latency: large videos and high-resolution media require more processing.
For important claims, follow the verification steps in our AI hallucinations guide.
A safe workflow for using multimodal AI
- Define the decision or output you need before uploading anything.
- Remove passwords, private identifiers, confidential records and unnecessary personal data.
- Use the smallest relevant file or crop rather than an entire archive.
- Explain what each input represents and what the model should examine.
- Ask the system to separate observations from assumptions.
- Verify quotations, numbers and conclusions against the original media.
- Keep a human reviewer responsible for publishing or acting on the result.
“Examine this [image/document/audio/video] for [specific purpose]. Describe only what is directly supported by the file. Separate observations from inferences, flag anything unclear, and list the exact page, timestamp or visual region supporting each important point.”
For more reliable instructions, use the goal, context, input, constraints and output structure in our AI prompting guide.
How to try multimodal creation with Unlimited AI
Unlimited AI brings chat, image, music and video tools into one website. You can begin with a written idea, compare how different assistants respond, then move to the media generator suited to the final output.
- Start with Unlimited AI and choose the tool that matches the task.
- Write a clear prompt that identifies the audience, format and constraints.
- Generate a small first version before investing in many variations.
- Check visual details, factual claims, audio quality and licensing.
- Edit the result and disclose generated media when people could mistake it for authentic evidence.
Multimodal AI FAQ
What is multimodal AI in simple terms?
It is AI that can work with more than one type of information, such as text and images or speech and video, and connect those inputs in one task.
Is ChatGPT multimodal AI?
Some ChatGPT models and experiences support combinations of text, images, audio or files. Exact capabilities depend on the current model, plan and interface, so check official product documentation.
What is an example of a multimodal prompt?
A user might upload a chart and ask, “Explain the main trend, identify the value in 2025 and tell me which parts of your answer come directly from the image.”
Is multimodal AI more accurate?
It can provide more context, but it is not automatically more accurate. Errors in image reading, transcription, source interpretation or reasoning still require verification.
Can multimodal AI understand video?
Some systems can analyze video frames, audio and captions. Limits vary by file length, resolution, supported format and whether the tool processes the entire video or selected frames.
What should I avoid uploading?
Avoid passwords, API keys, private financial or health records, confidential business files, intimate media and personal data you do not have permission to share.
Final takeaway
Multimodal AI makes digital tools more natural because people can communicate with words, pictures, sound, video and documents. Its value comes from connecting those formats, but the same flexibility increases privacy, accuracy and consent risks. Use only the inputs a task needs, give precise instructions and verify the final result at its original source.