Last reviewed: October 7, 2026. Search for “quiet place to work” in a library of office listings. A keyword system may miss a page that says “low-noise coworking studio.” A meaning-based search system can retrieve it because the ideas are related, even though the exact words differ. Vector databases help make that kind of search fast across large collections.
This guide explains what a vector database stores, how embeddings and similarity search work, when keyword search is better, and how to evaluate the results. You do not need to know the mathematics to understand the practical choices.
What Is a Vector Database?
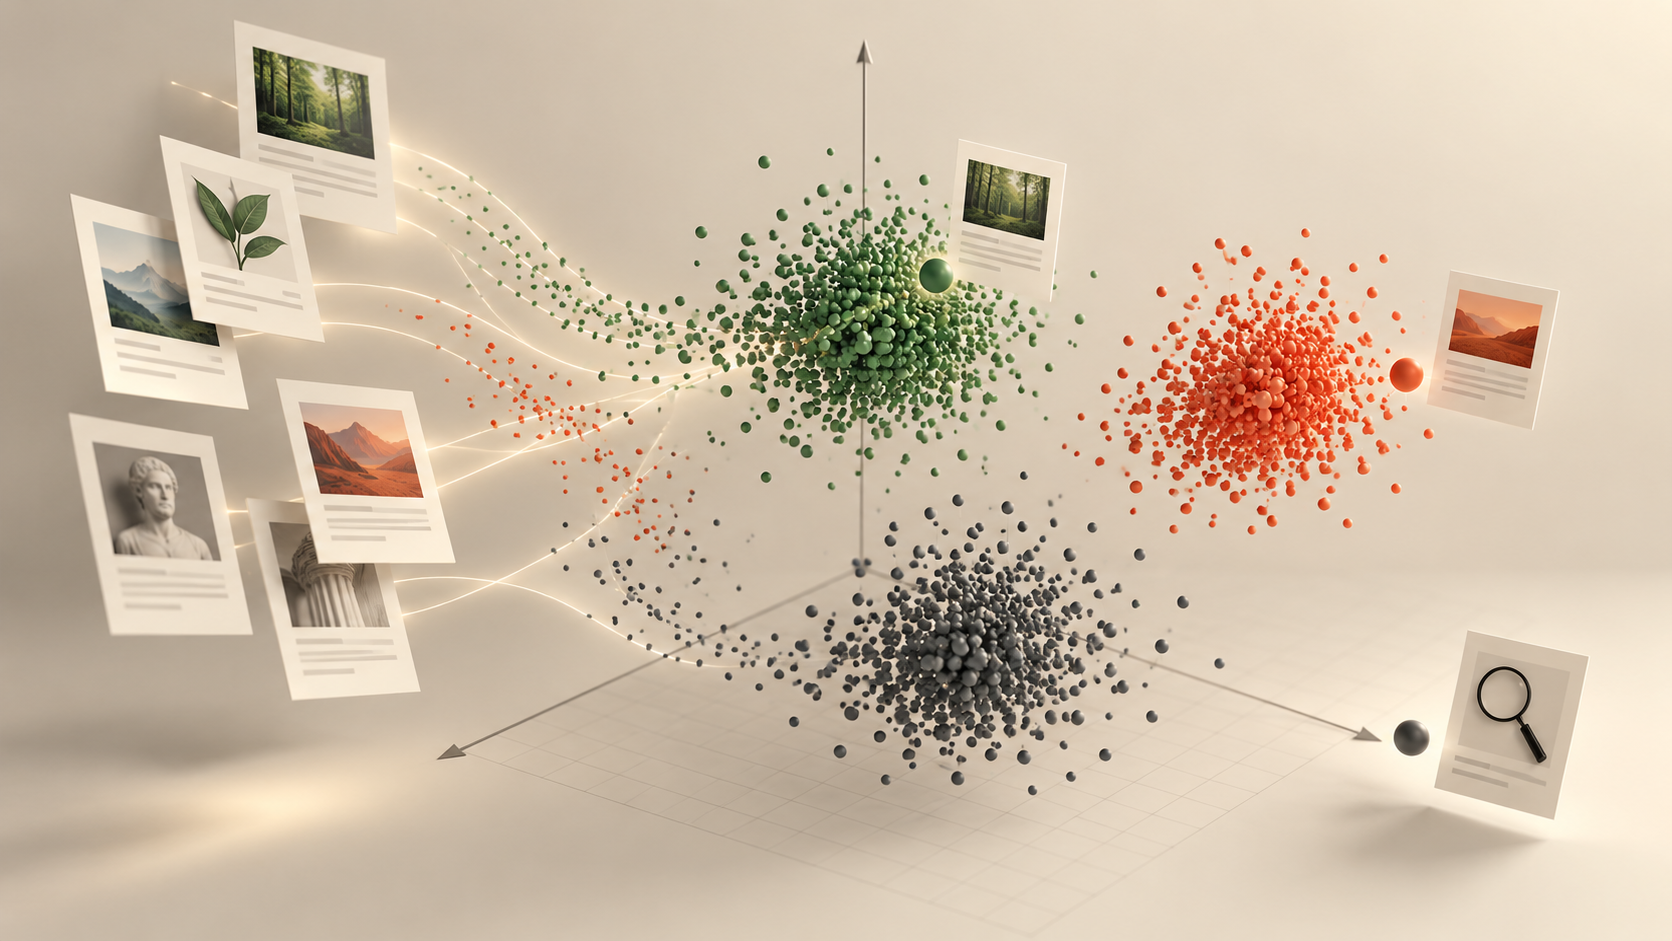
A vector database is a system for storing and searching numerical representations of content, called vectors or embeddings. An embedding model converts text, an image or another item into a sequence of numbers. Items with similar meanings or features are often located near one another under a chosen distance measure. The database uses those numbers to find likely matches.
The database does not understand the content in a human sense. Its search quality depends on the embedding model, the data, the query, the index and any filters. A closer vector is a candidate result—not proof that a document answers the question.
An embedding is a compact numeric description. Vector search asks, “Which stored descriptions are closest to this query?” The application then shows the original documents, products or images linked to those vectors.
How Do Embeddings Work?
An embedding model processes an item and outputs a fixed-length vector, such as hundreds or thousands of numbers. The values themselves are not useful to read one by one. Their arrangement lets a similarity function compare items in the model’s learned space. A search query must be embedded using a compatible model before it can be compared with stored vectors.
For example, “how do I cancel an order?” and “steps to reverse a purchase” might be close enough to retrieve the same support policy. “Order lunch for the office” shares a word but describes a different task. An effective embedding can help distinguish these cases, although performance varies by model and domain.
A vector can represent more than text. Image embeddings can help find visually similar products; audio embeddings can support sound matching; multimodal systems can connect text queries to images. Each use needs an appropriate model and evaluation set.
The Vector Search Workflow, Step by Step
- Prepare content: Collect approved documents, product records or images and keep their original identifiers.
- Divide long material: Split lengthy documents into useful passages while preserving titles, dates and access rules.
- Create embeddings: Run each item or passage through an embedding model.
- Store vectors and metadata: Keep each vector with a reference to the original item and useful fields such as category, date or permission.
- Embed the query: Convert the user’s request with a compatible model.
- Retrieve candidates: Search for close vectors, apply permitted filters and rank the results.
- Show or use the source: Return the human-readable original content, or pass it to another system with links and context.
The search index is only one part of the workflow. If the original documents are stale, the vector database can efficiently return stale content. If a document is private, access must be enforced before it appears in results.
A Concrete Example: Product Search
Imagine a shop selling desk lamps. A customer searches for “reading light for a small bedroom.” The catalogue may describe a product as “compact adjustable bedside lamp” without using the customer’s exact phrase. Vector search can surface it based on related meaning.
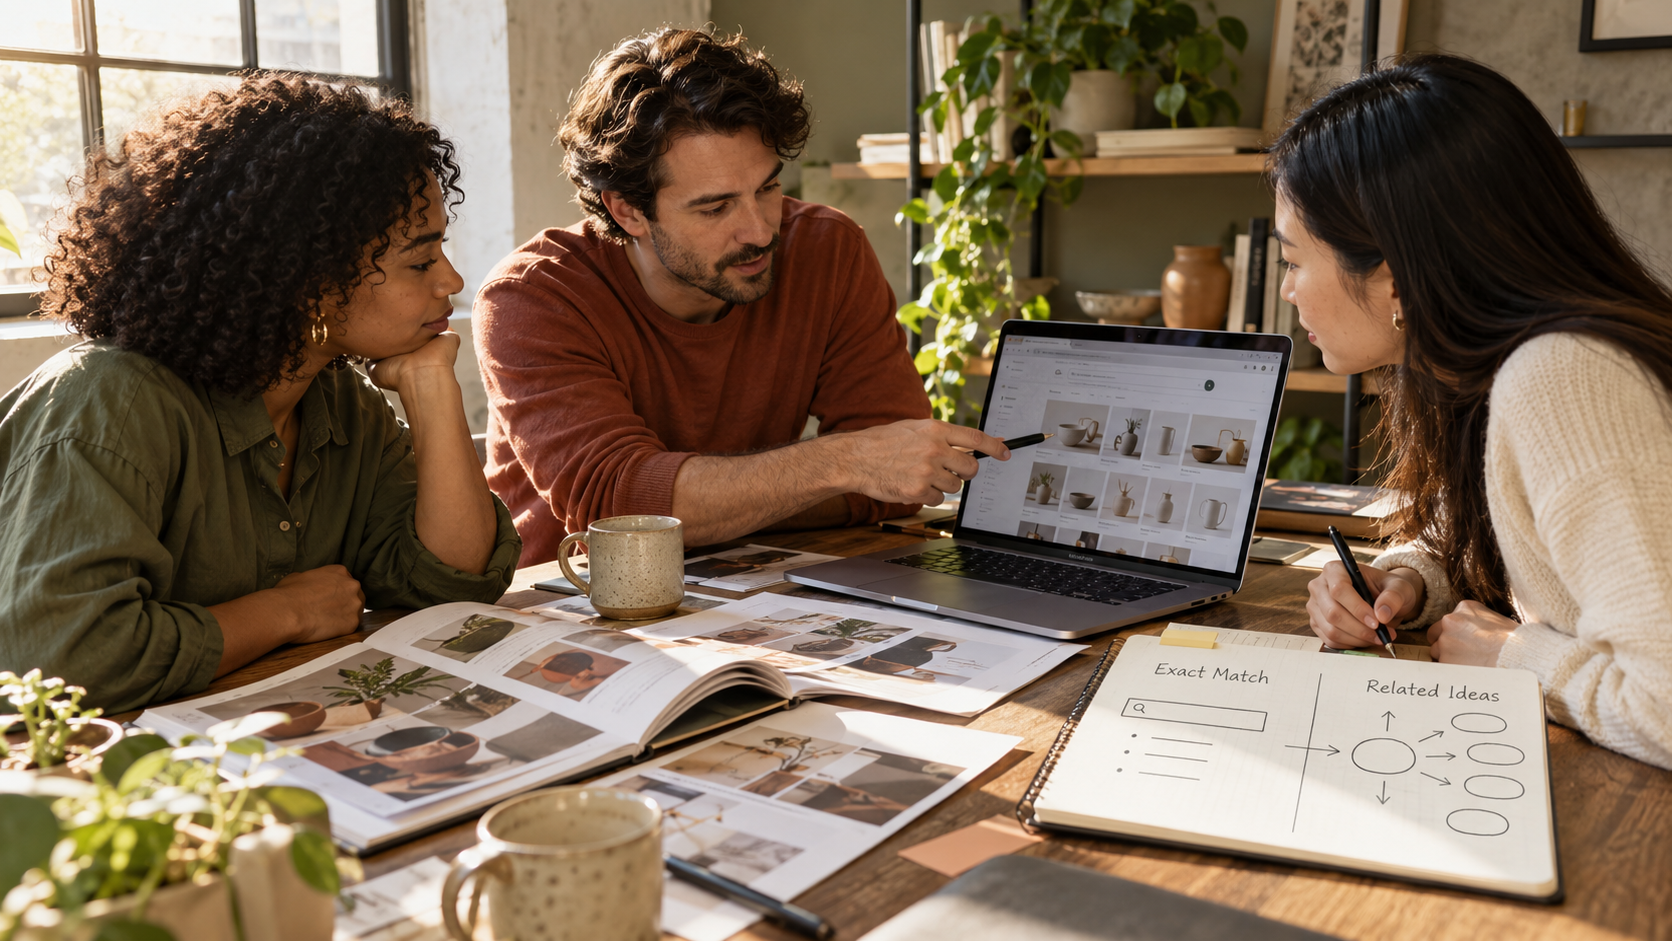
But the same shop also sells a model named “LAMP-42.” Someone searching for that product code expects an exact match. A meaning-based system might return broadly similar lamps instead. This is why real search products often combine keyword and vector methods.
Vector Search vs. Keyword Search vs. Hybrid Search
| Method | Finds well | Can miss | Good example |
|---|---|---|---|
| Keyword search | Exact words, IDs, names and codes | Different wording with the same meaning | “LAMP-42” |
| Vector search | Conceptually similar items | Precise names, numbers or policy conditions | “compact reading light” |
| Hybrid search | Both exact and meaning-based matches | Still needs ranking and evaluation | Product search across codes and descriptions |
Microsoft’s hybrid search documentation describes running text and vector searches together and merging the results. Its guidance notes that names, dates, product codes and specialized terminology can favor keyword matching, while vectors help with conceptual similarity. Hybrid search is often a stronger starting point than assuming one technique will solve every query.
A system may also rerank its first set of results using a more expensive model. That can improve relevance but adds latency and cost. Test the whole search pipeline on real user queries before choosing more components.
What Makes Vector Search Fast?
A simple comparison could measure every stored vector against the query. That exact nearest-neighbor search can work for small collections but may become expensive as the index grows. Many systems use an approximate nearest-neighbor index to search faster by narrowing the candidates.
“Approximate” means the fastest index may occasionally miss an item that an exhaustive search would find. This is a tunable trade-off between speed, memory use and recall. The pgvector project supports exact search and approximate indexes including HNSW and IVFFlat, and its documentation explicitly notes the speed-versus-recall trade-off.
Recall asks how many relevant or exact-nearest results the system found. Latency asks how long the query took. A faster index that misses important answers may be a poor choice for a support or research assistant.
Do You Need a Specialized Vector Database?
Not always. If you already use PostgreSQL, a vector extension may be enough for a modest workload. A search service can also combine text and vector fields in one index. A dedicated vector database may help when scale, filtering, update frequency or operational needs justify another system.
| Option | Consider it when | Watch for |
|---|---|---|
| Existing relational database with vector support | You want vectors beside existing records and queries | Index tuning, scale and search-specific features |
| Search service with vector and text search | You need hybrid retrieval and familiar search controls | Service cost, filtering behavior and ranking design |
| Dedicated vector database | Similarity retrieval is central at large scale | Extra infrastructure and data synchronization |
Microsoft’s vector index overview shows that vector fields can coexist with text and numeric fields in a search index. This is a helpful reminder: the relevant design choice is the whole retrieval system, not the product label.
Where Vector Databases Help
Retrieval-augmented generation
A common use is retrieving relevant passages before a language model answers a question. The vector database returns candidate passages; the model uses them as context. Our RAG guide explains the complete answer workflow and why citations still need checking. RAG does not require vectors—keyword or hybrid retrieval may be better for a particular collection.
Recommendations and discovery
A recommendation system can use embeddings to find products, articles or media similar to an item a user liked. Similarity alone is not a full recommendation strategy: availability, diversity, safety, freshness and user preferences also matter.
Duplicate detection and organization
Teams can find near-duplicate documents, cluster related support tickets or organize large media libraries. Human review is useful when a close match might be a legitimate variant rather than a duplicate.
Image and multimodal search
A customer might type “green ceramic mug with a curved handle” to search images. If the text and images are mapped into a compatible space, the system can retrieve relevant photos without relying only on tags. Results still need visual and product-attribute checks.
Common Failure Modes
The nearest result may still be wrong
A query can always have a nearest vector even when the collection contains no answer. A support assistant should be able to say “I could not find a relevant policy” rather than treating the top hit as proof. Thresholds and answer verification help, but they must be tested.
Numbers, names and exact strings can fail
Embeddings are designed for similarity, not exact equality. Product IDs, law sections, version numbers and dates often need keyword matches or structured filters. A small change in a number can have a large real-world effect even if the surrounding text looks similar.
Chunking can remove context
If a long document is split into tiny passages, a retrieved paragraph may lose the heading or condition that changes its meaning. If chunks are too large, a relevant detail may be buried. Preserve source title, section, version and surrounding context.
Private content can leak through retrieval
A vector database can retrieve a sensitive passage just as readily as a public one. Permission checks must be applied to the source records and results. Do not assume that numeric embeddings are harmless simply because they are hard to read directly.
Indexes can become stale
When documents change, their embeddings and metadata may need updating. Delete superseded versions, track update failures and test whether a new query finds the current source. Our context engineering guide explains why current, relevant context matters for downstream AI answers.
How to Evaluate a Vector Search System
Start with a small set of real queries from the people who will use the product. For each one, identify useful results and obvious wrong answers. Include ordinary wording, synonyms, exact codes, ambiguous questions, rare cases and no-answer queries. Then compare keyword, vector and hybrid setups on the same set.
- Relevance: Are the top results actually helpful for the task?
- Recall: Does the system find important relevant items somewhere in the candidate set?
- Exact-match behavior: Do names, IDs and numbers remain reliable?
- Latency and cost: Are response times and indexing expenses acceptable?
- Freshness: Do recent changes appear, and are old versions removed?
- Access control: Can each user retrieve only content they are allowed to see?
- Answer quality: If an AI writes from retrieved passages, does the final answer accurately reflect them?
There is no useful single “best vector database” without a workload. A benchmark with millions of short product descriptions may not predict results for a small policy library with complex permissions. Test with your own documents, queries and constraints.
Frequently Asked Questions
Is a vector database the same as an embedding model?
No. The embedding model creates the numerical representations. The database stores and searches them. Both affect the quality of the final result.
Does vector search understand meaning perfectly?
No. Embeddings can capture useful relationships, but they can miss negation, rare terminology, exact numbers or domain-specific distinctions. Evaluate important cases and keep exact search where it helps.
Can a regular database store vectors?
Yes. PostgreSQL with pgvector is one example. Some search services also store vectors beside text and numeric fields. A separate database is a design choice, not a requirement.
Does RAG require a vector database?
No. RAG needs a way to retrieve relevant source material before generation. That retrieval can be keyword search, vector search, hybrid search or another method.
What is hybrid search?
It combines conventional text matching with vector similarity so an application can catch both exact terms and related meanings. The result sets are then merged or reranked.
Final Takeaway
Vector databases make similarity search practical, but the most useful search experience depends on the whole pipeline: good source data, a suitable embedding model, exact matching where necessary, access controls and evaluation on real queries. Begin with the user’s search problem, then choose the simplest retrieval design that solves it.